Image genRecorded August 26, 202610 models
The cat on the sofa
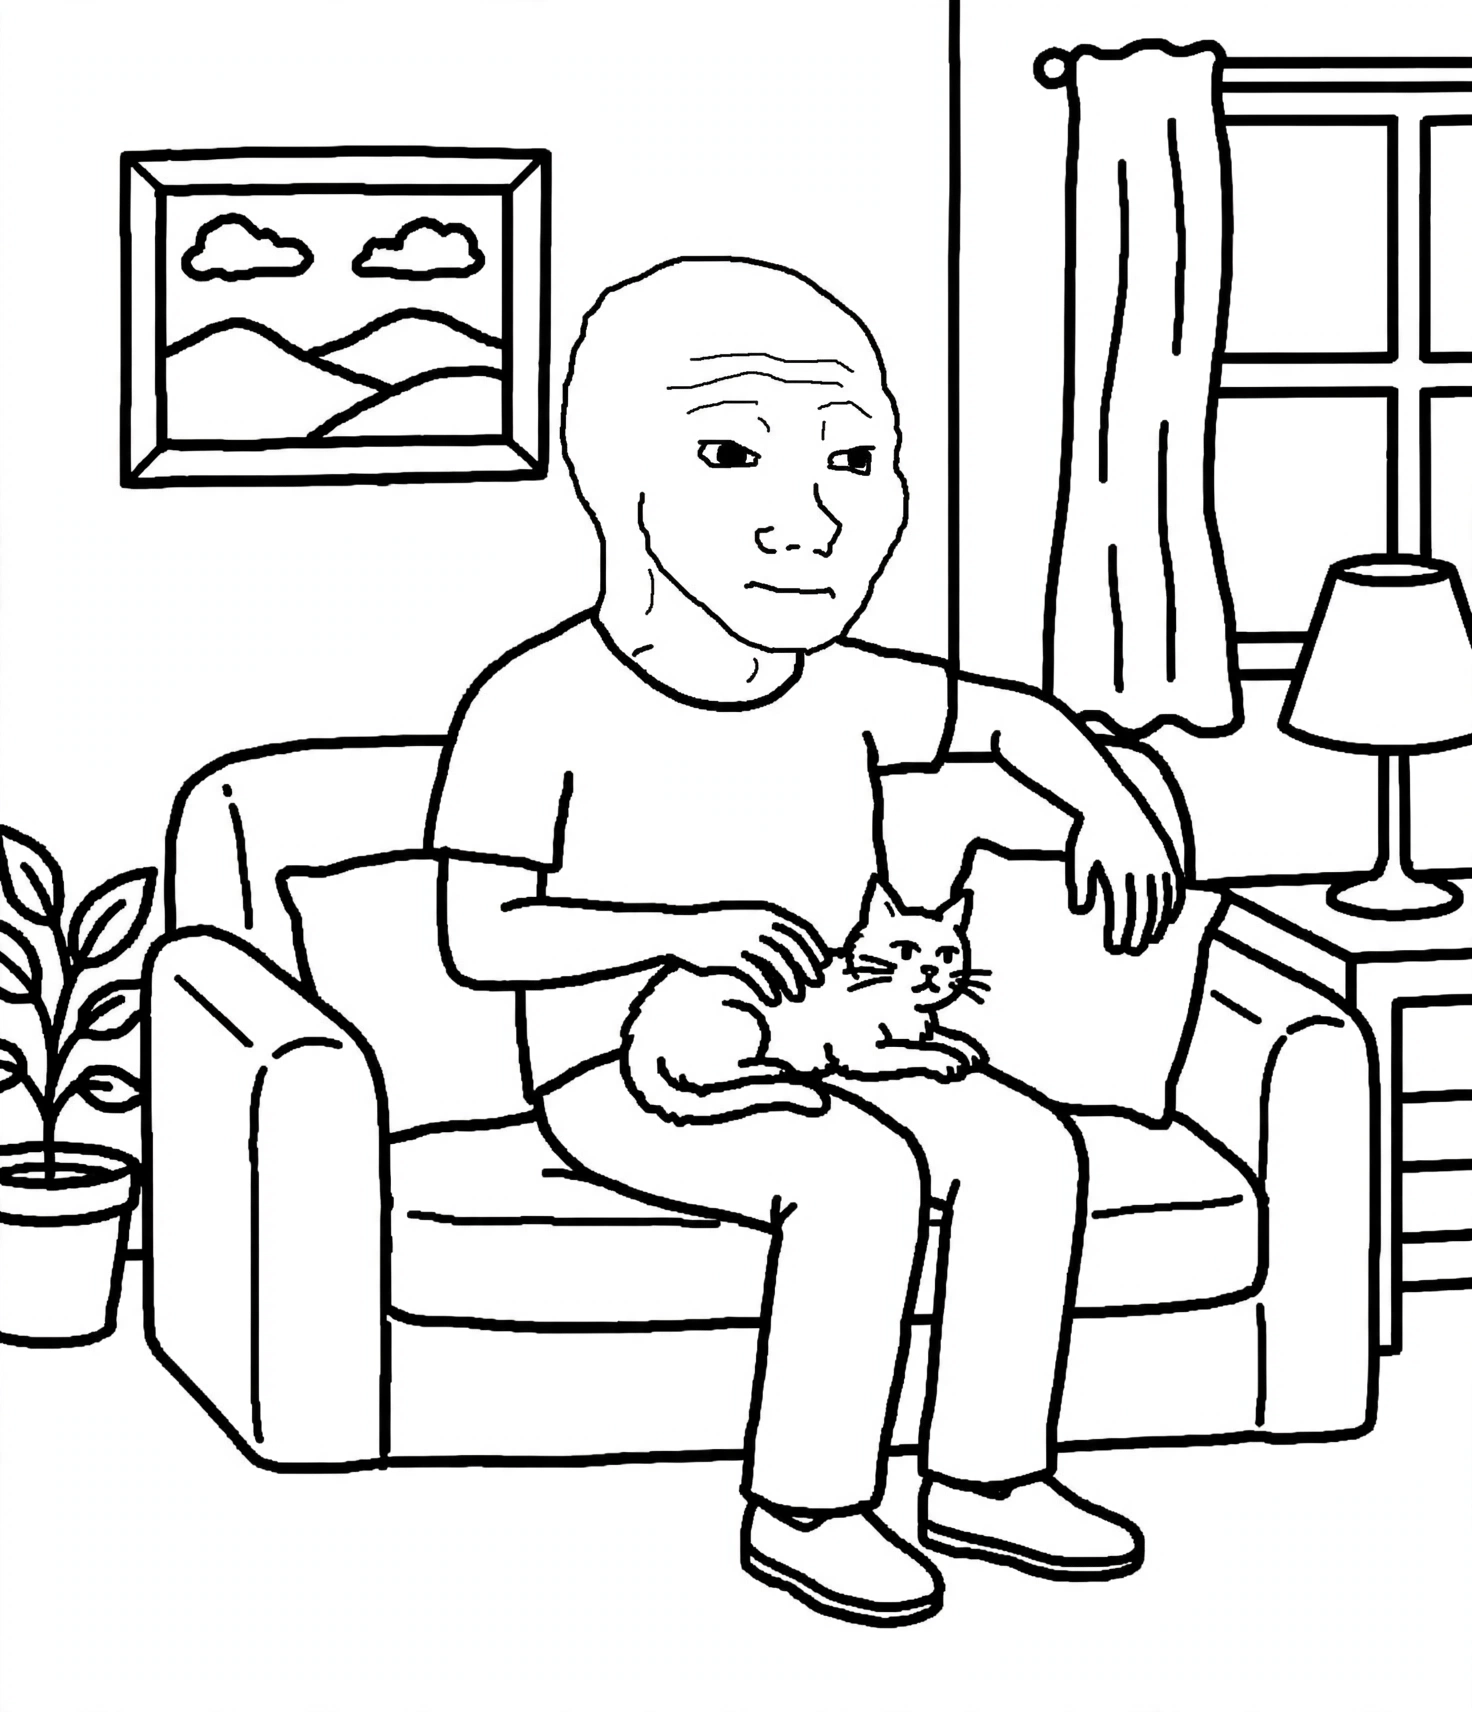
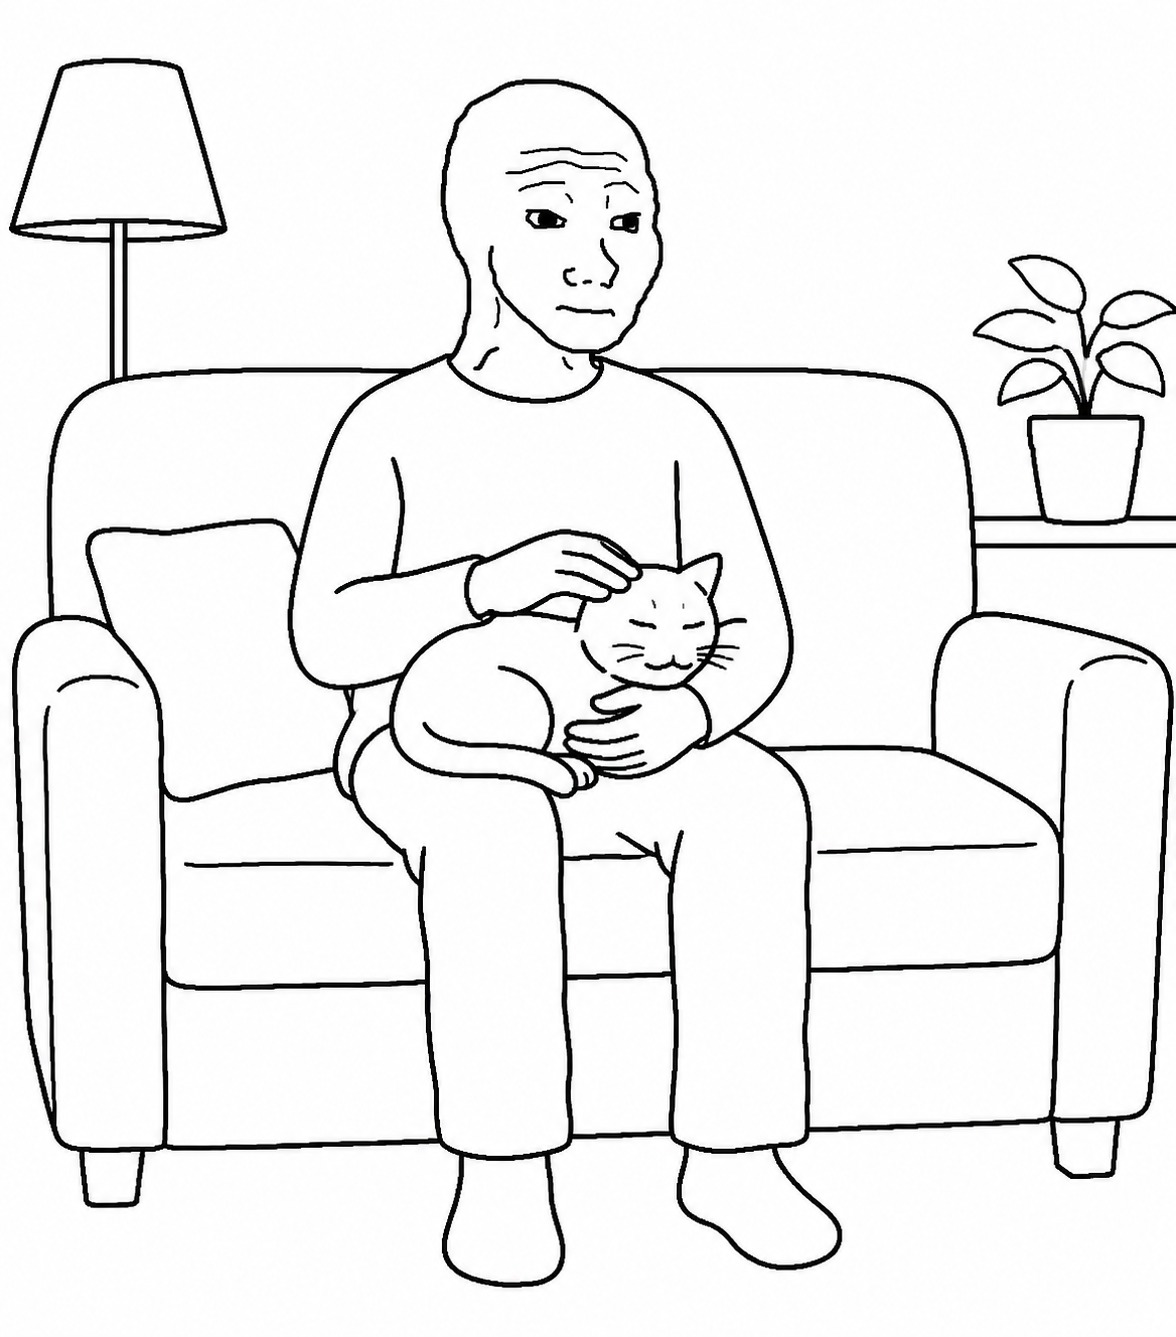
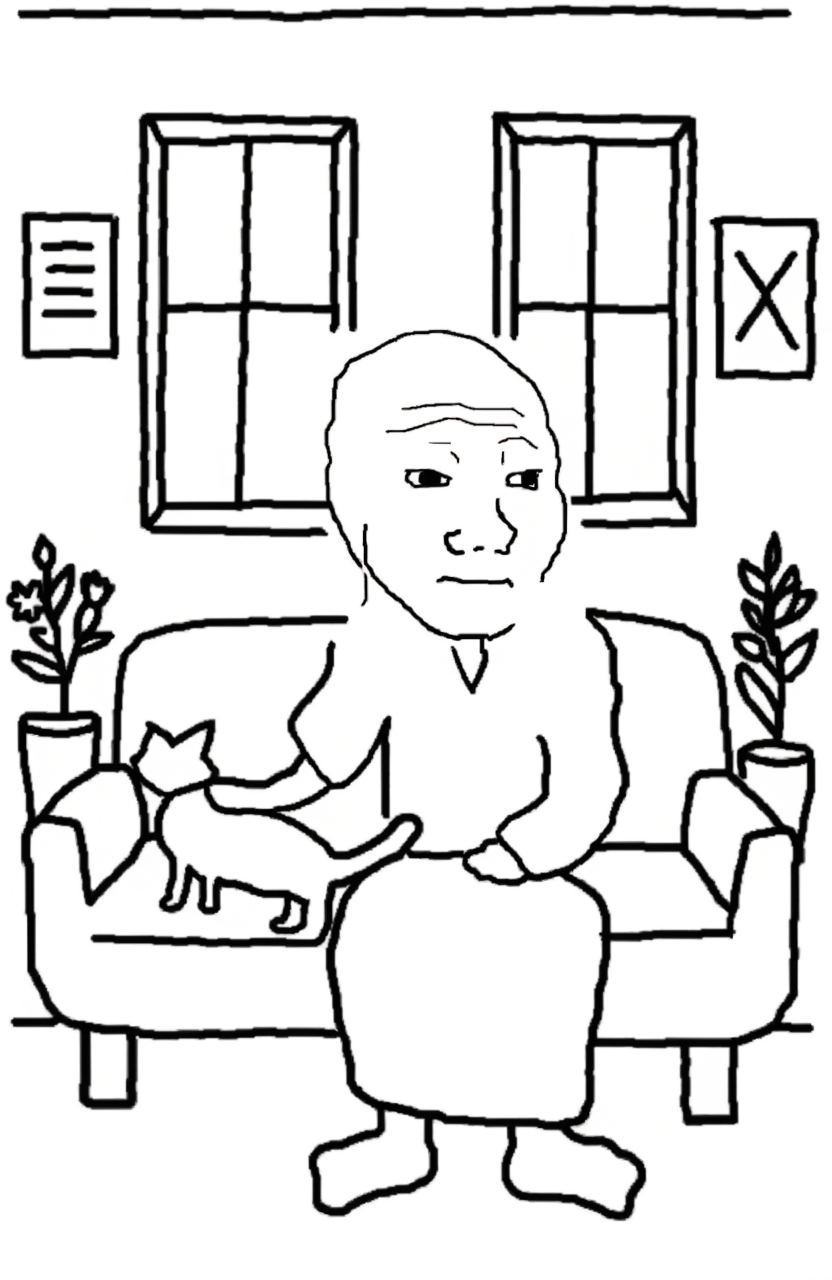
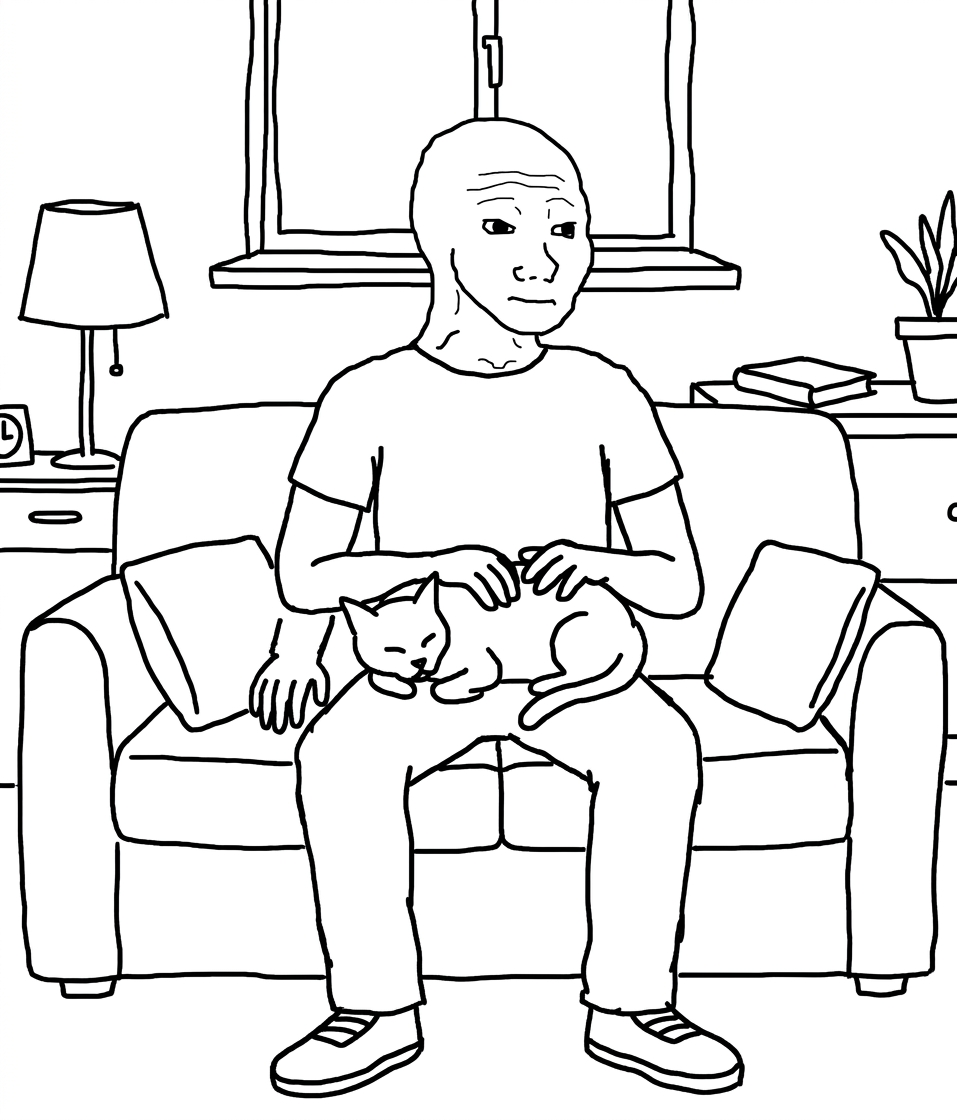
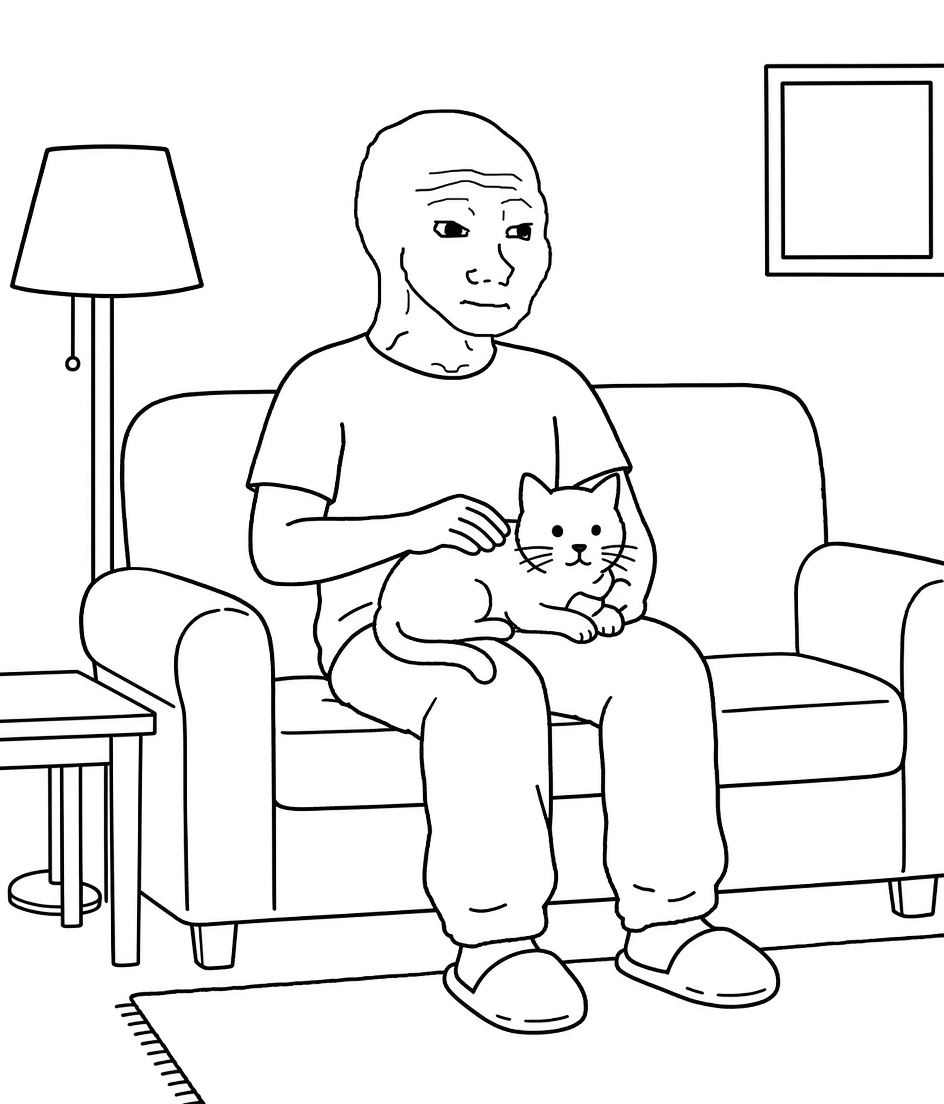
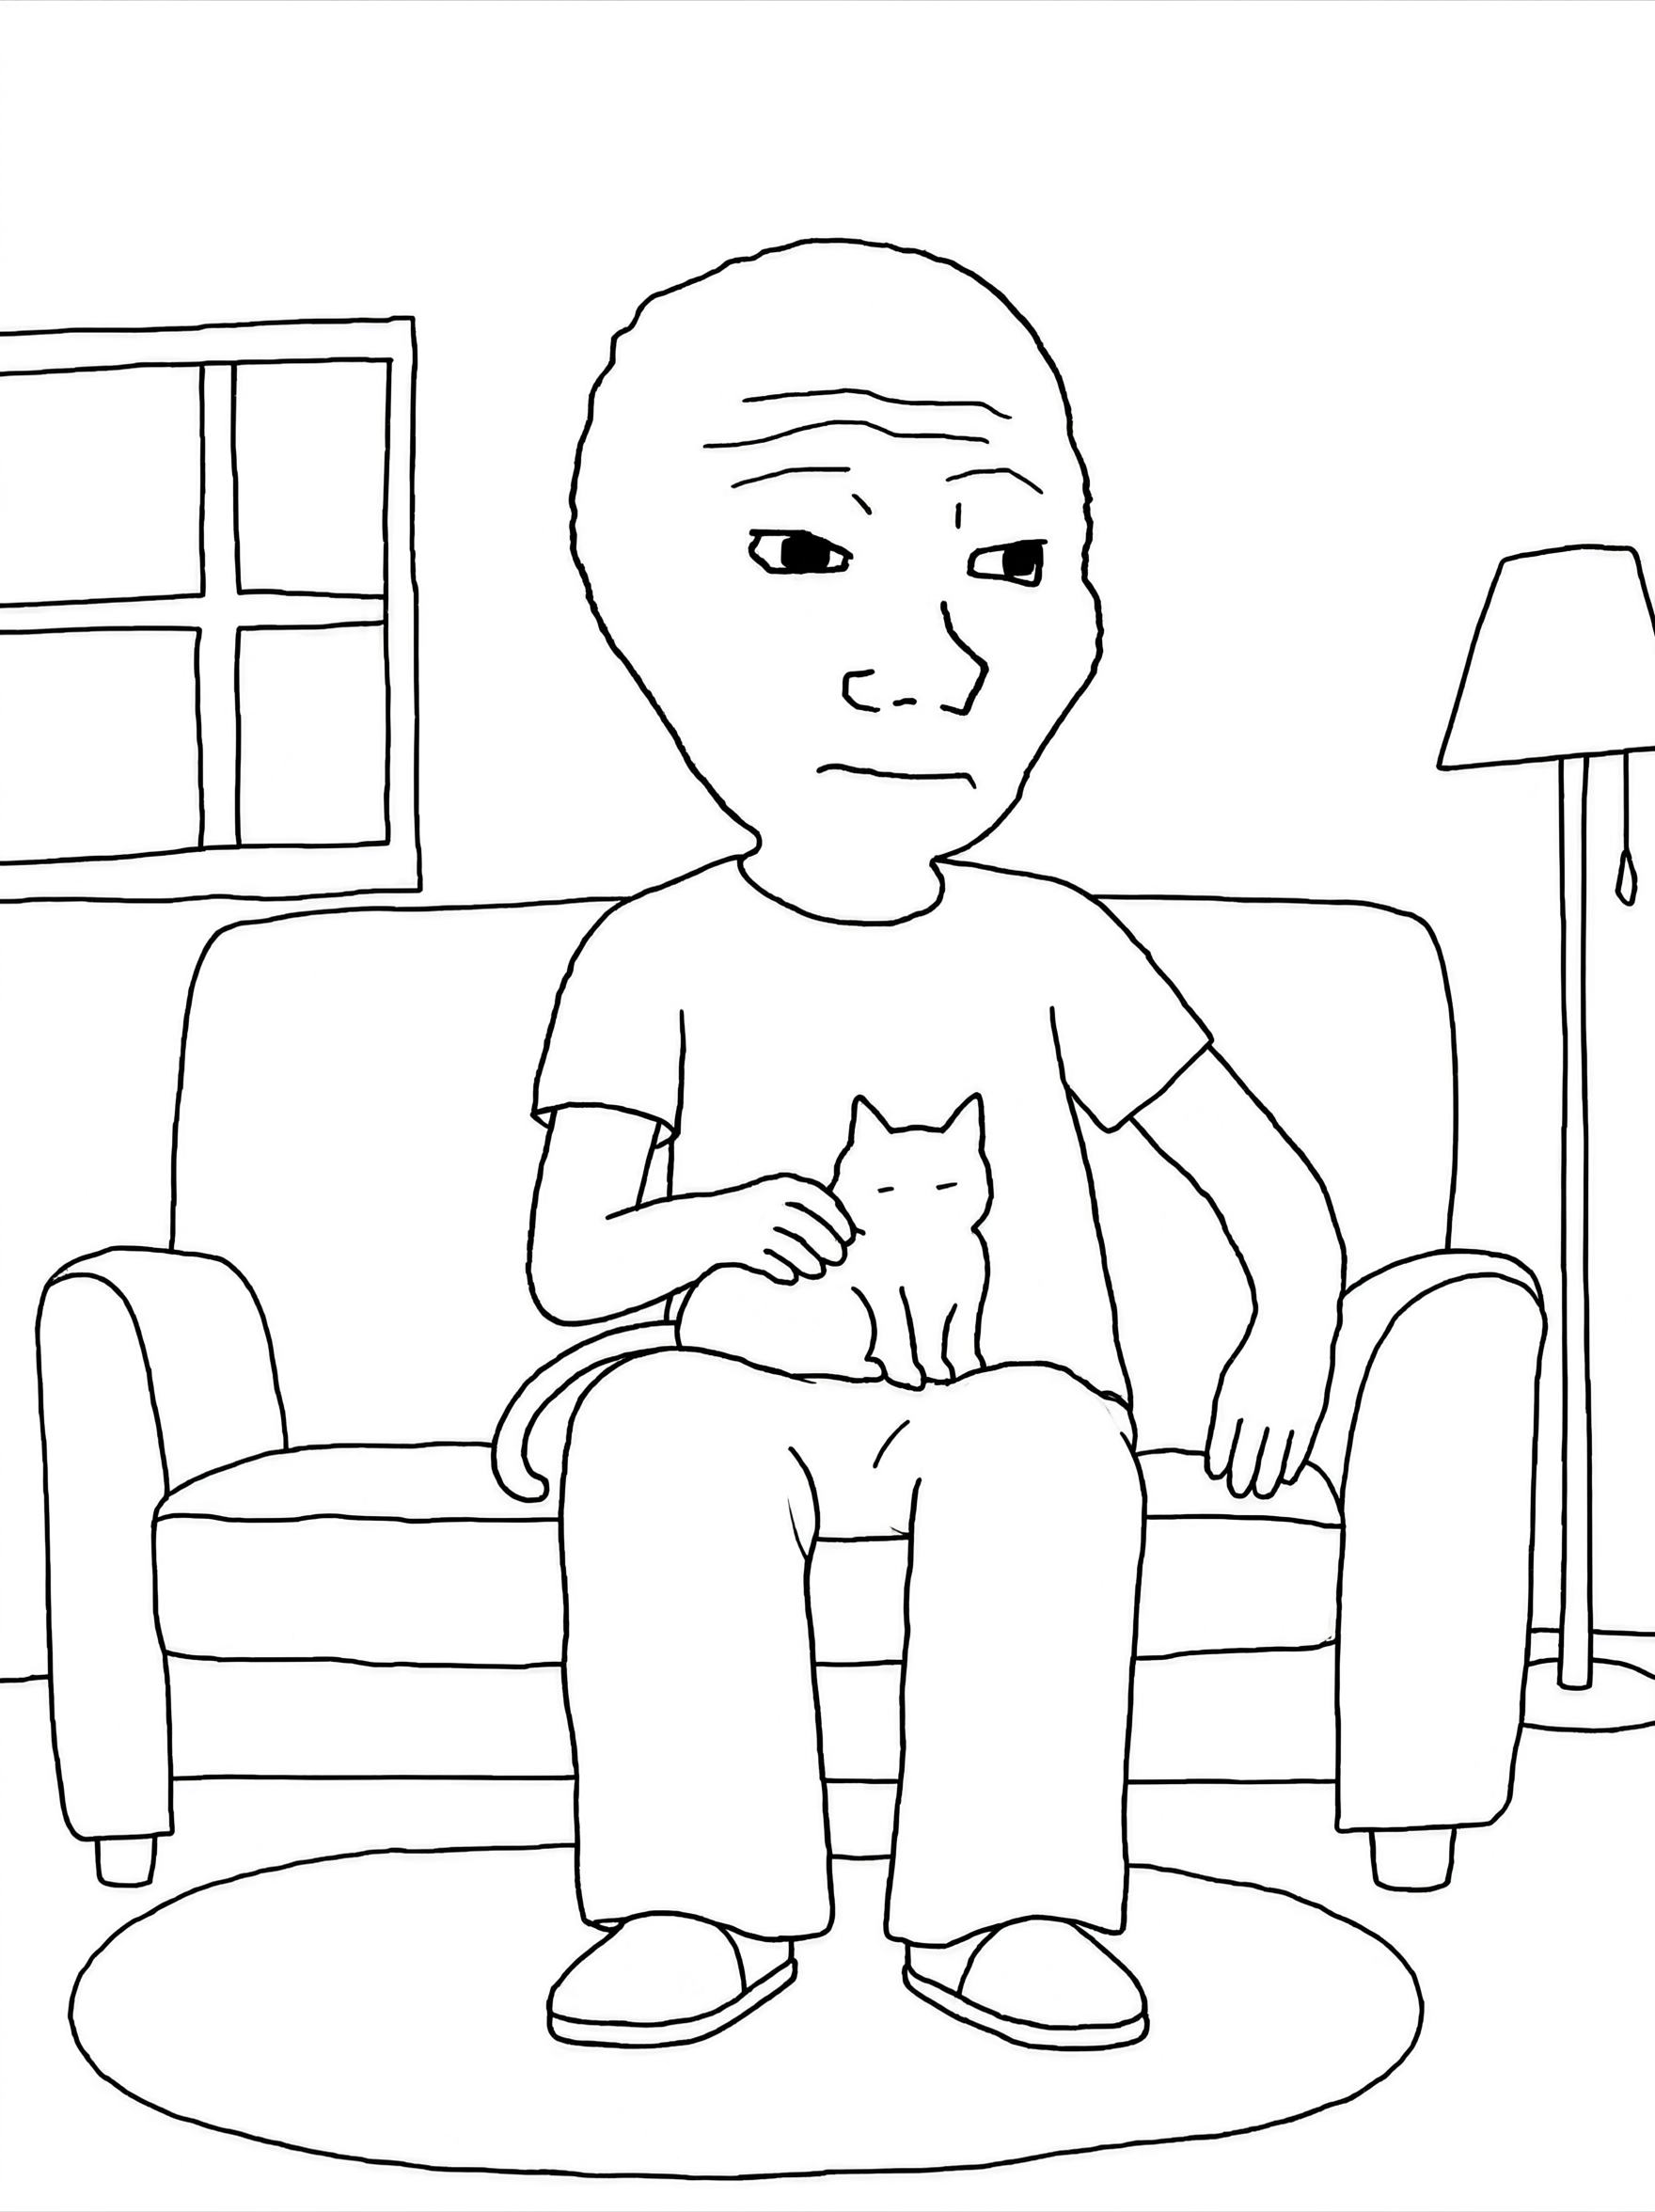
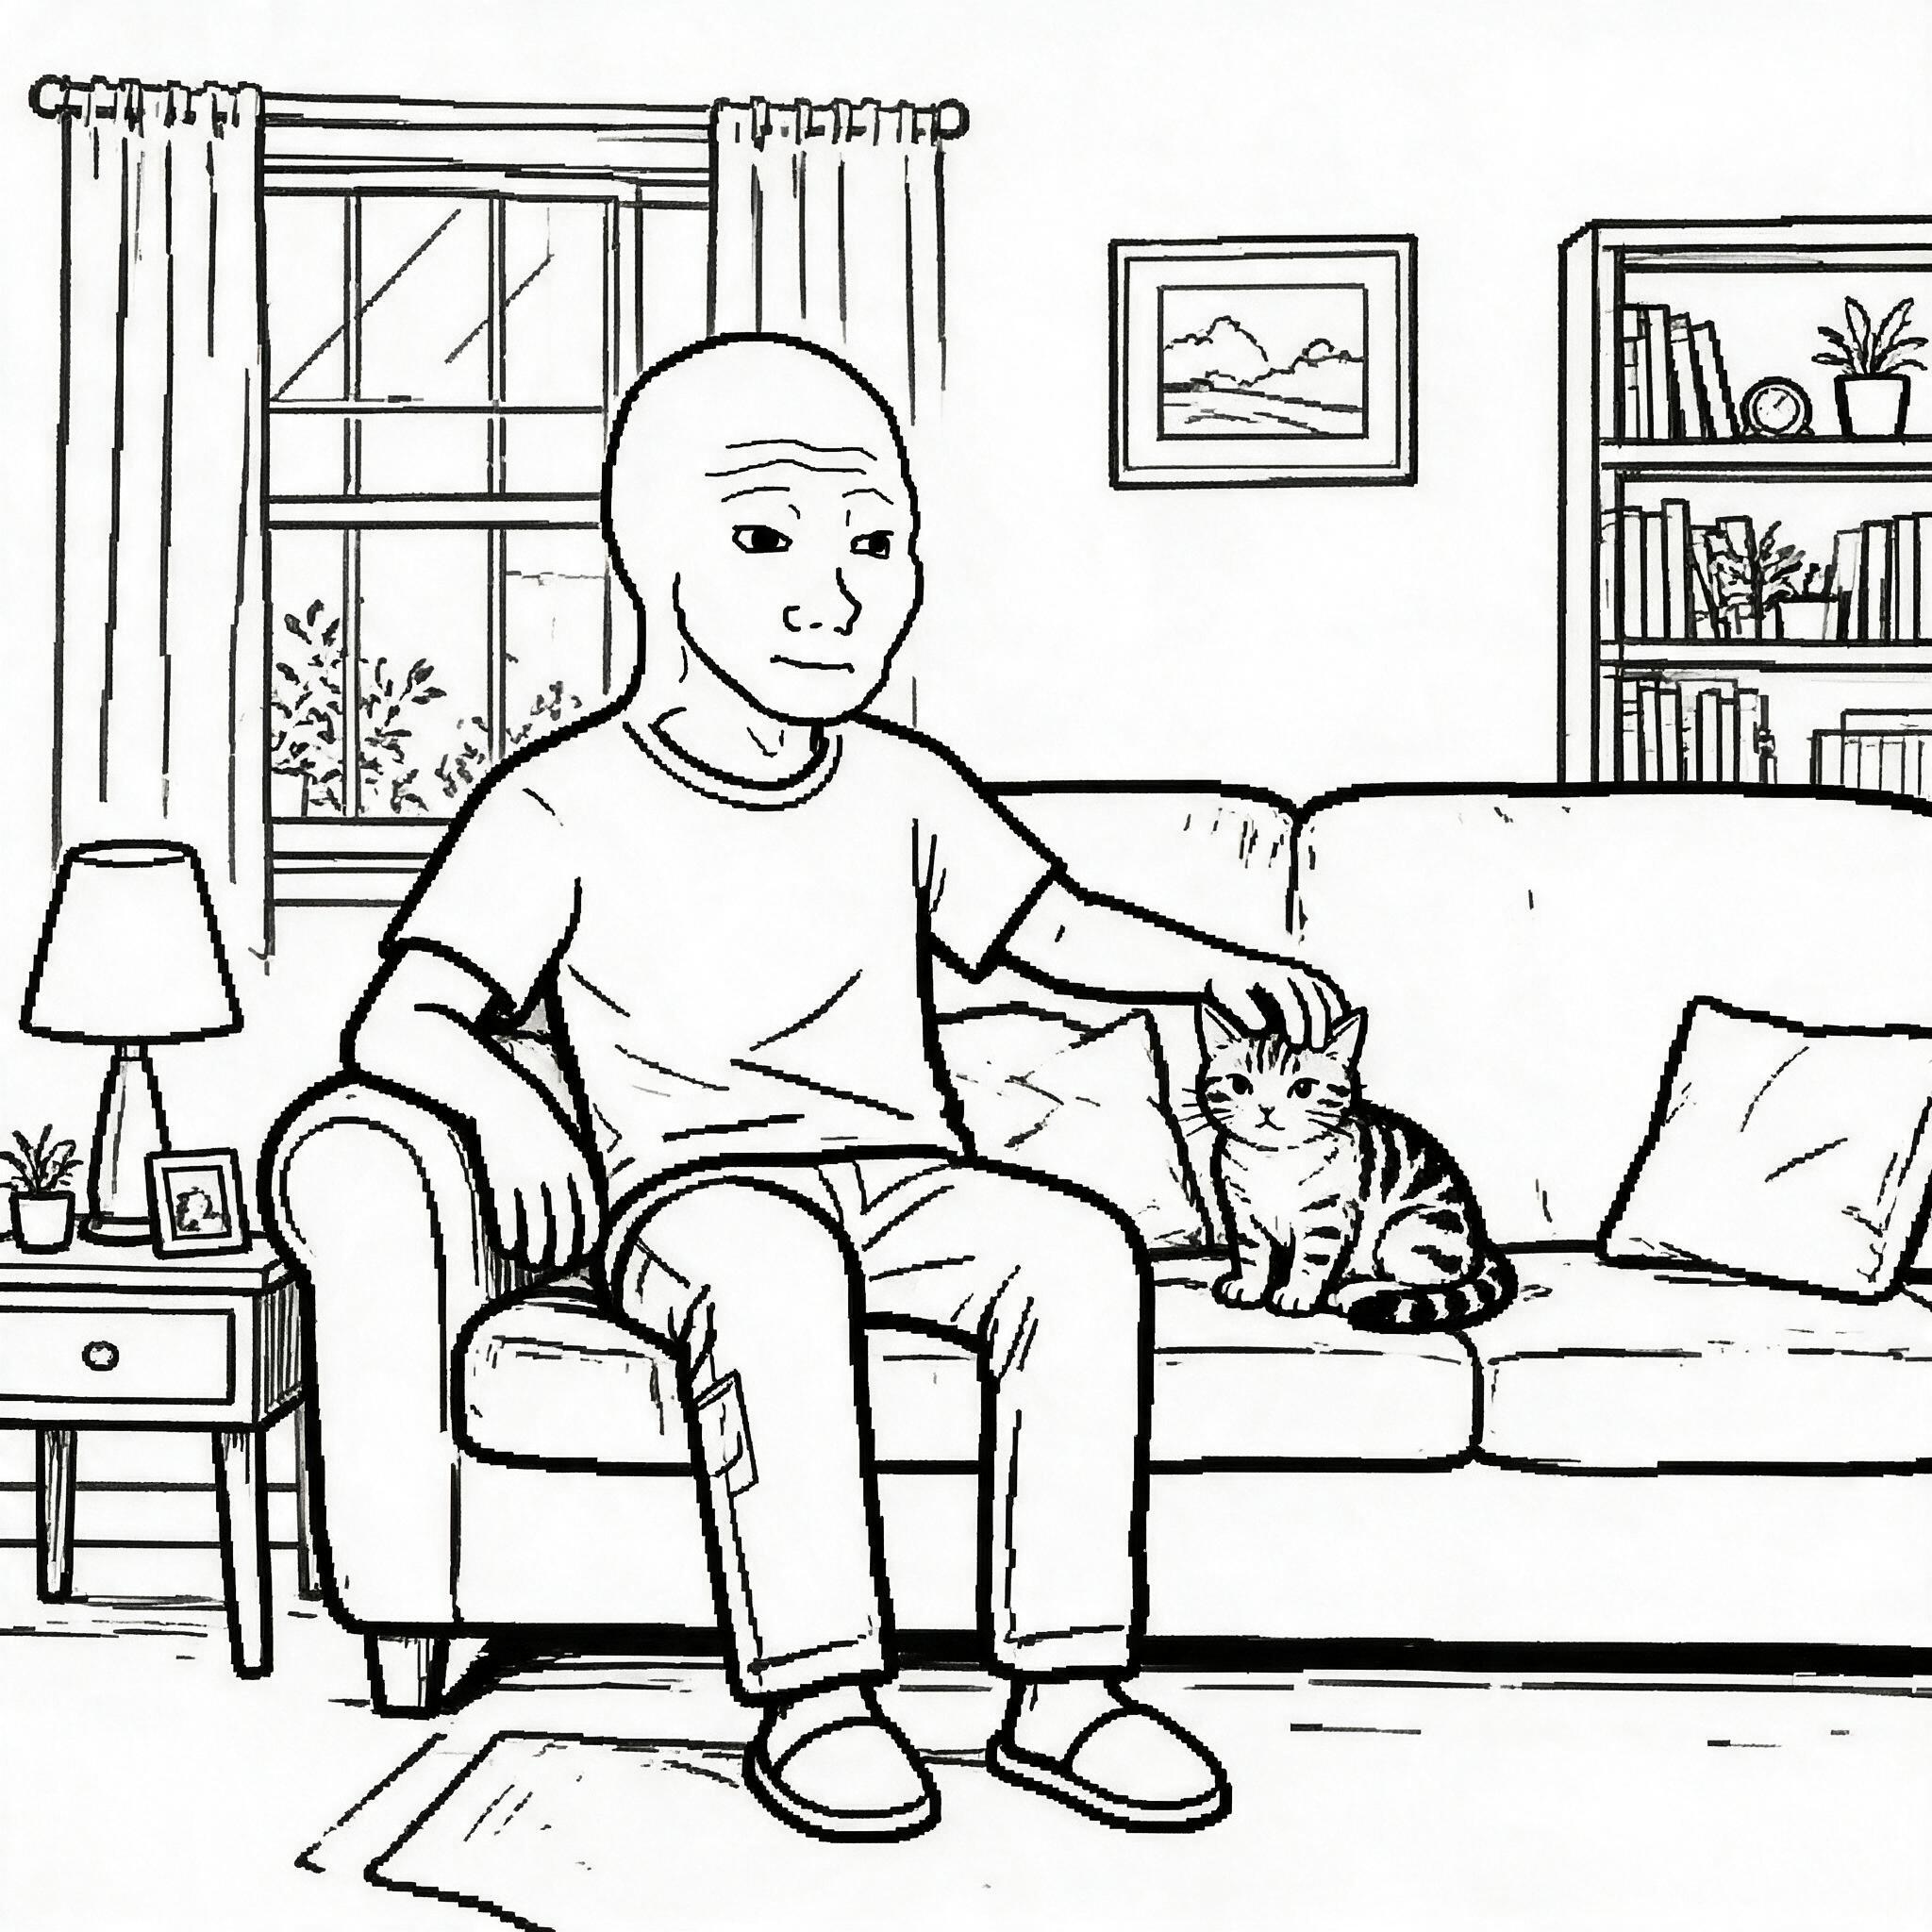
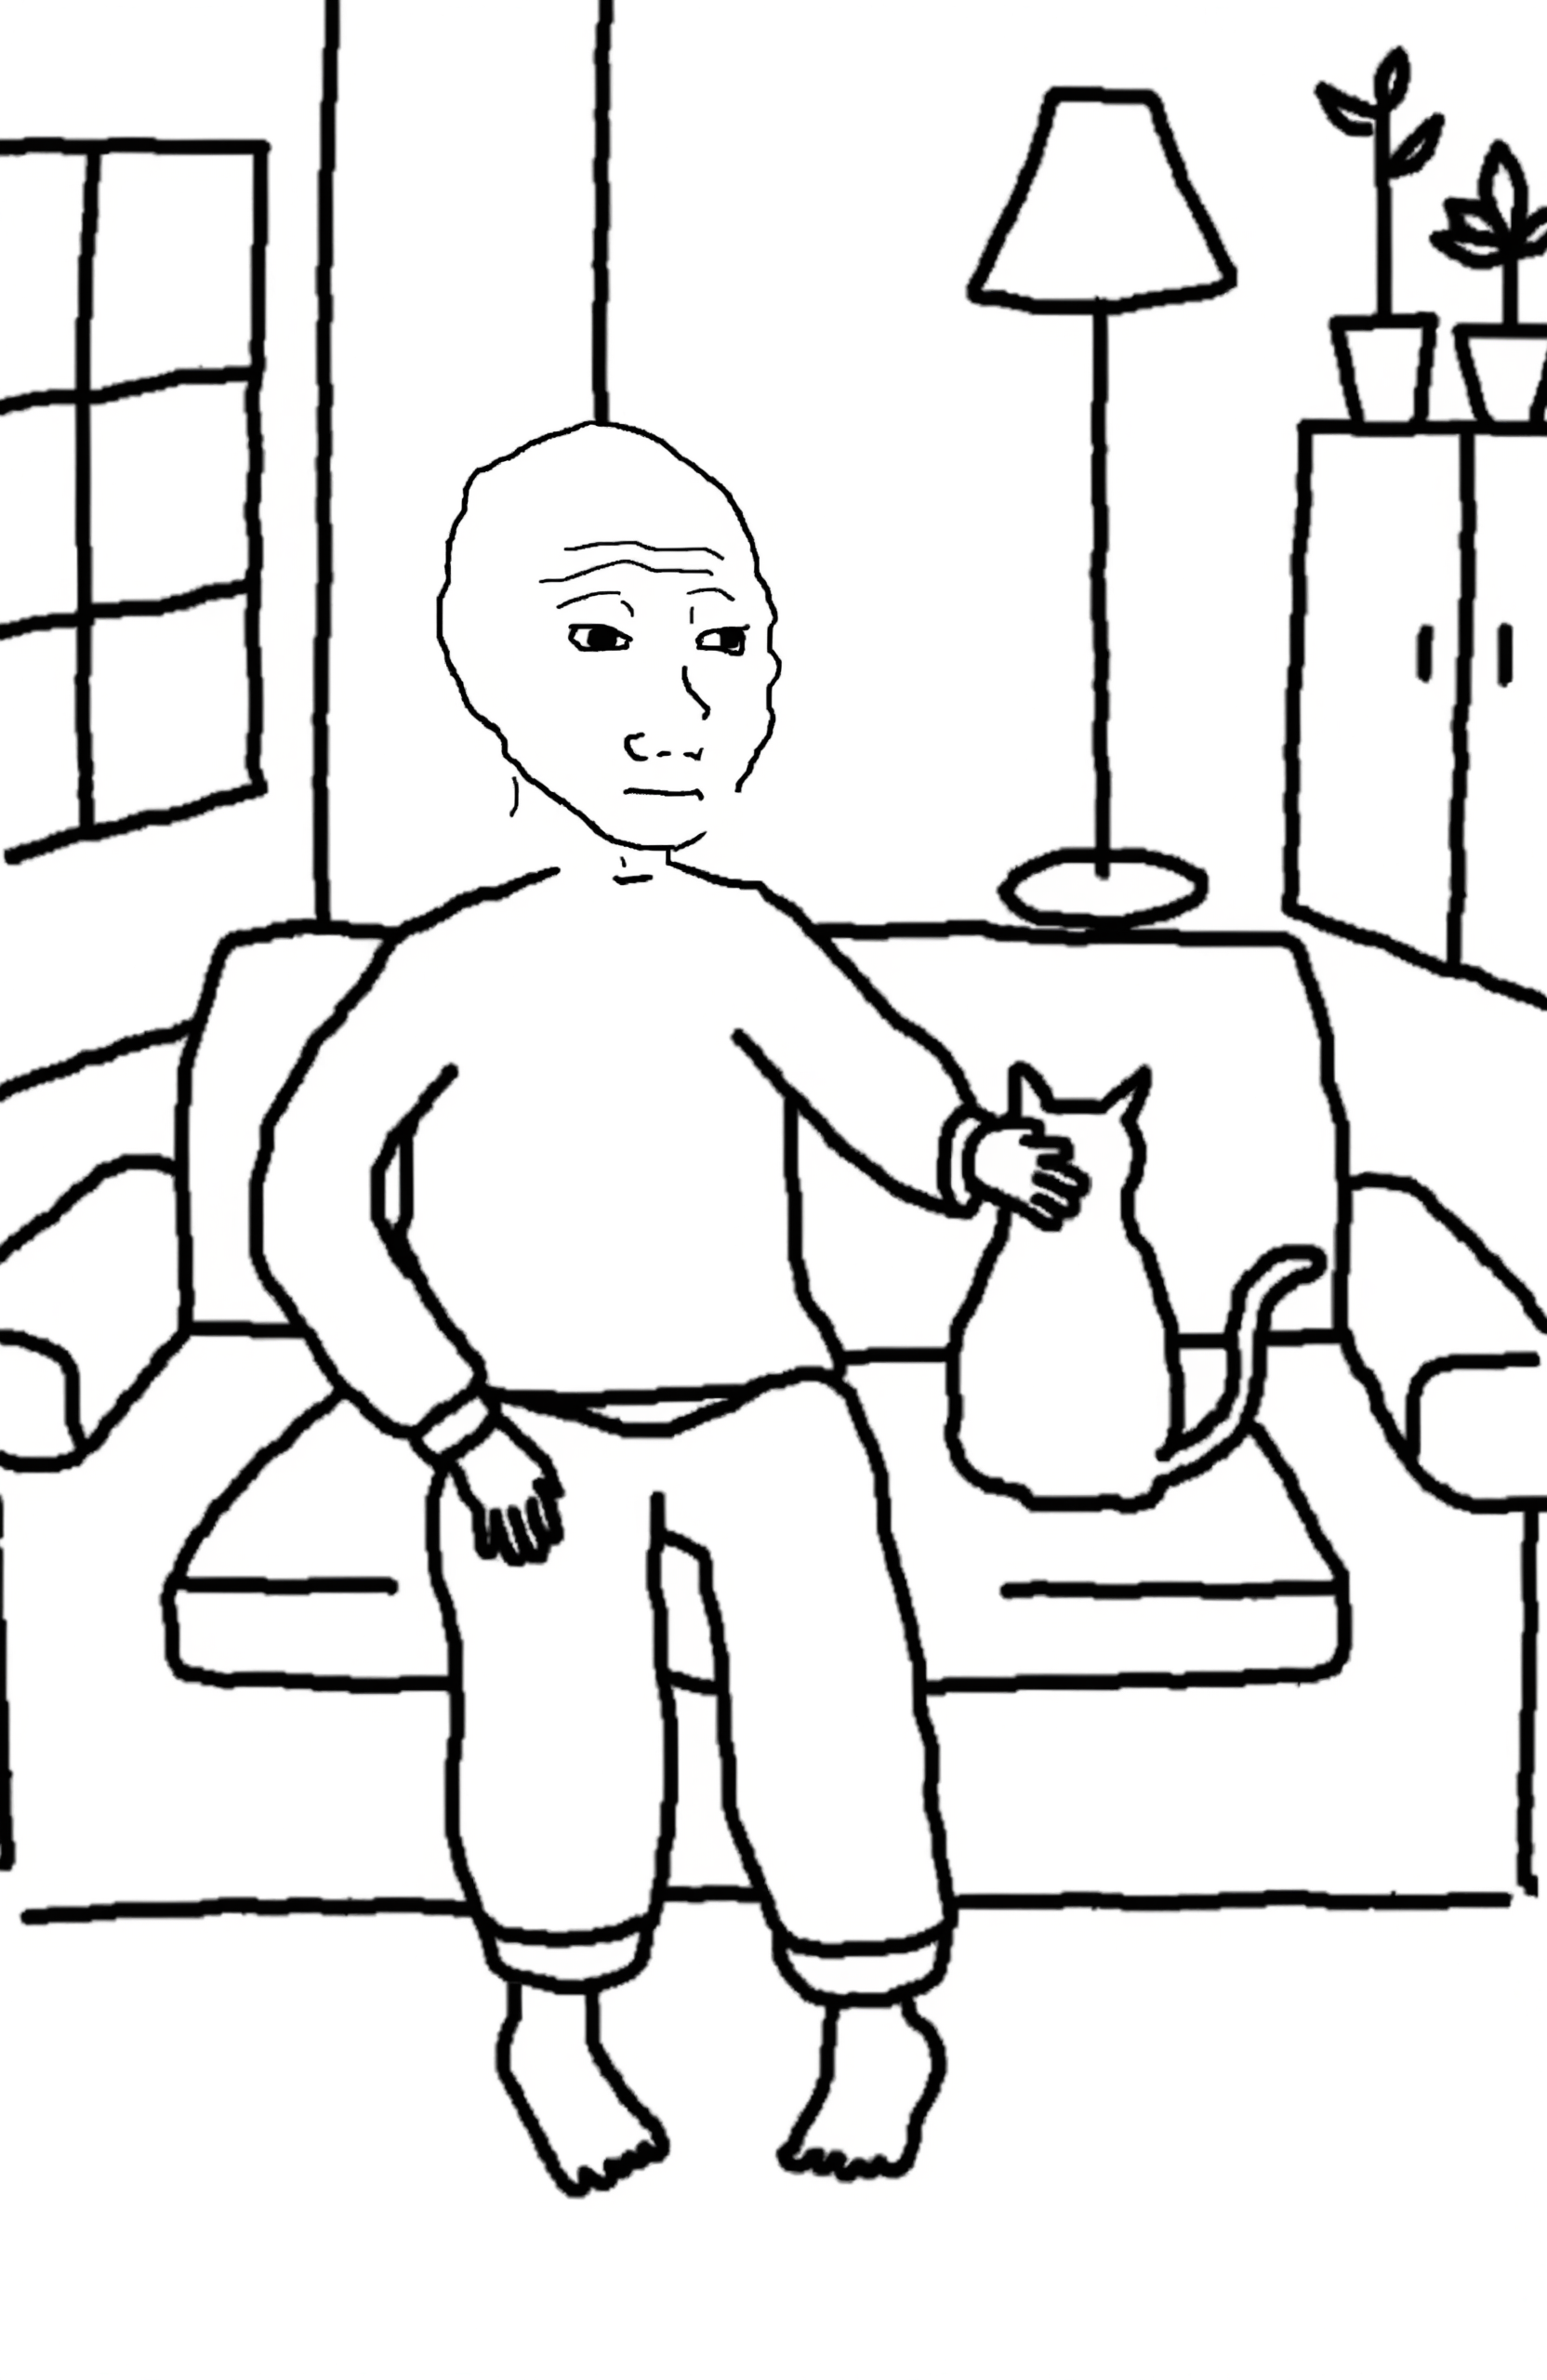
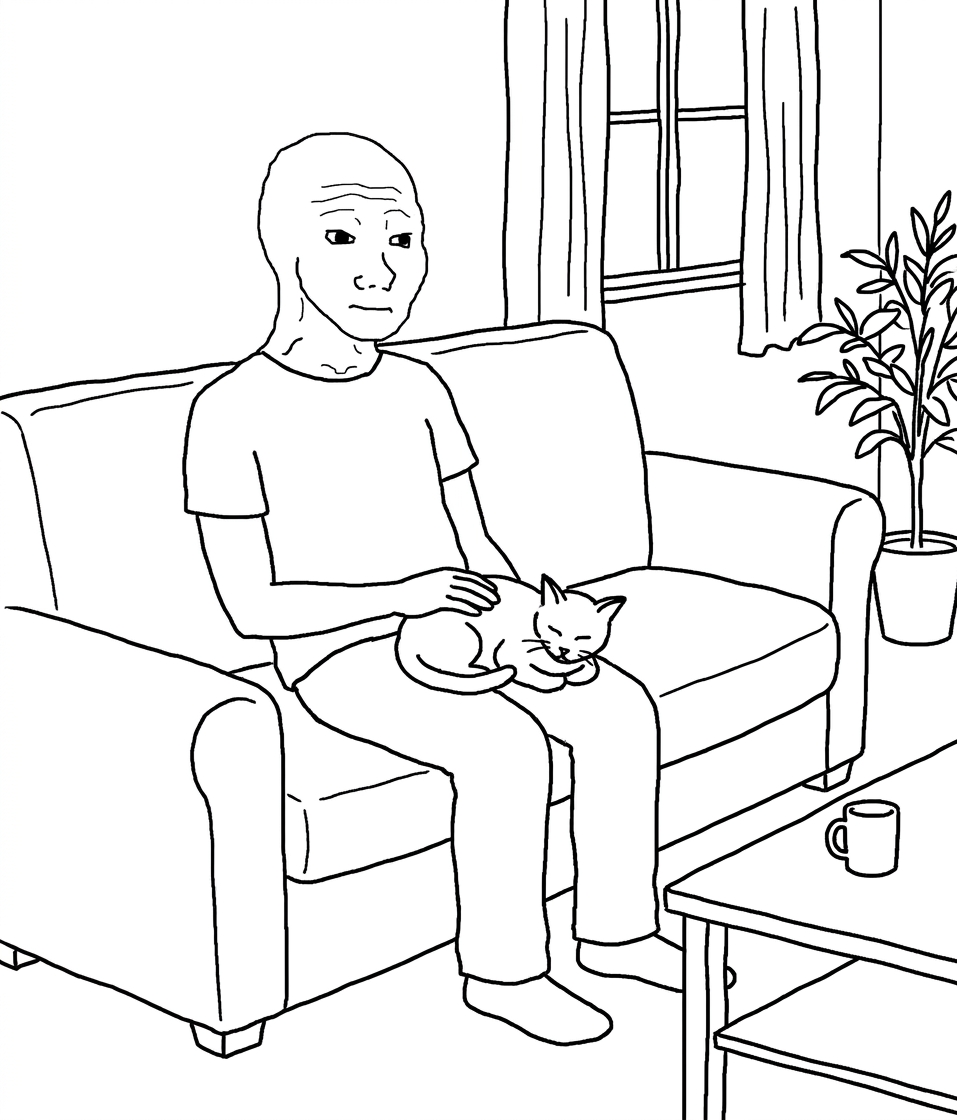
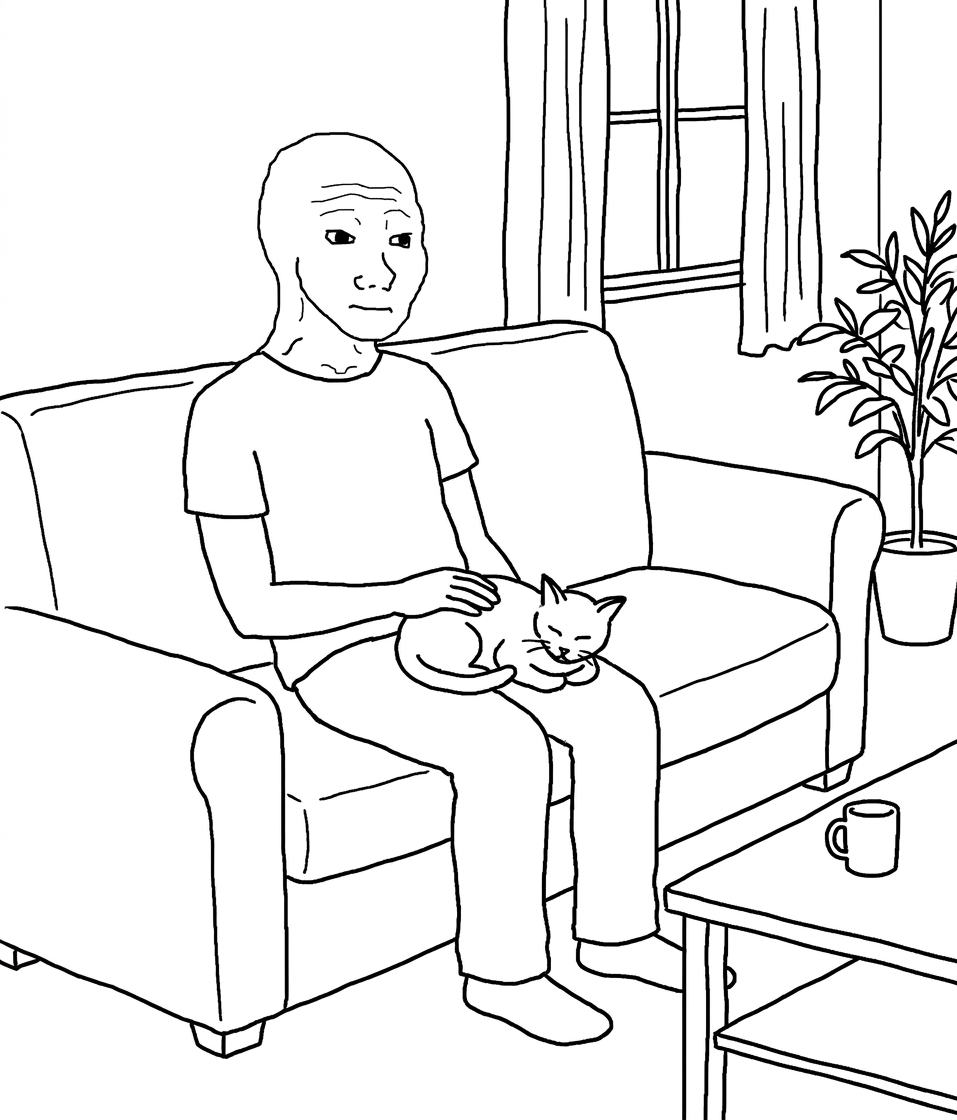
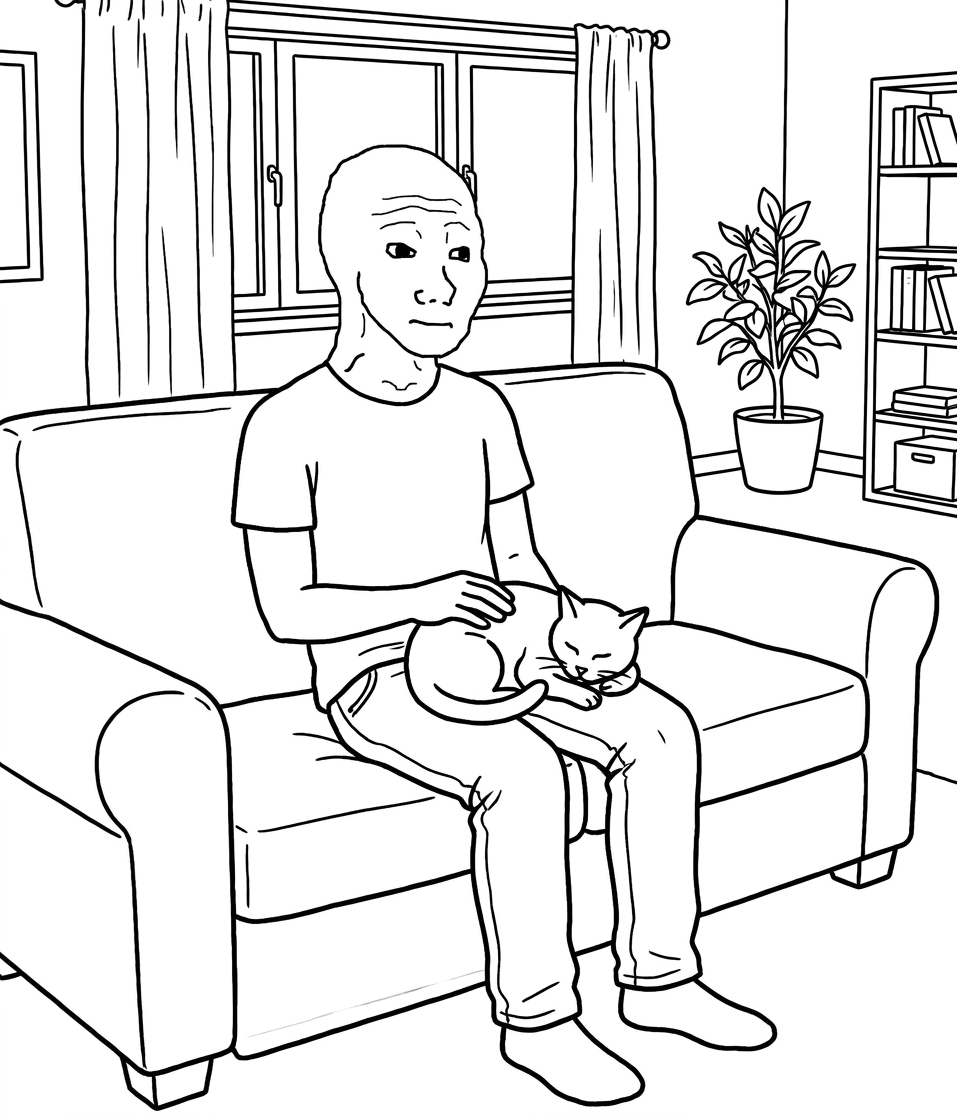
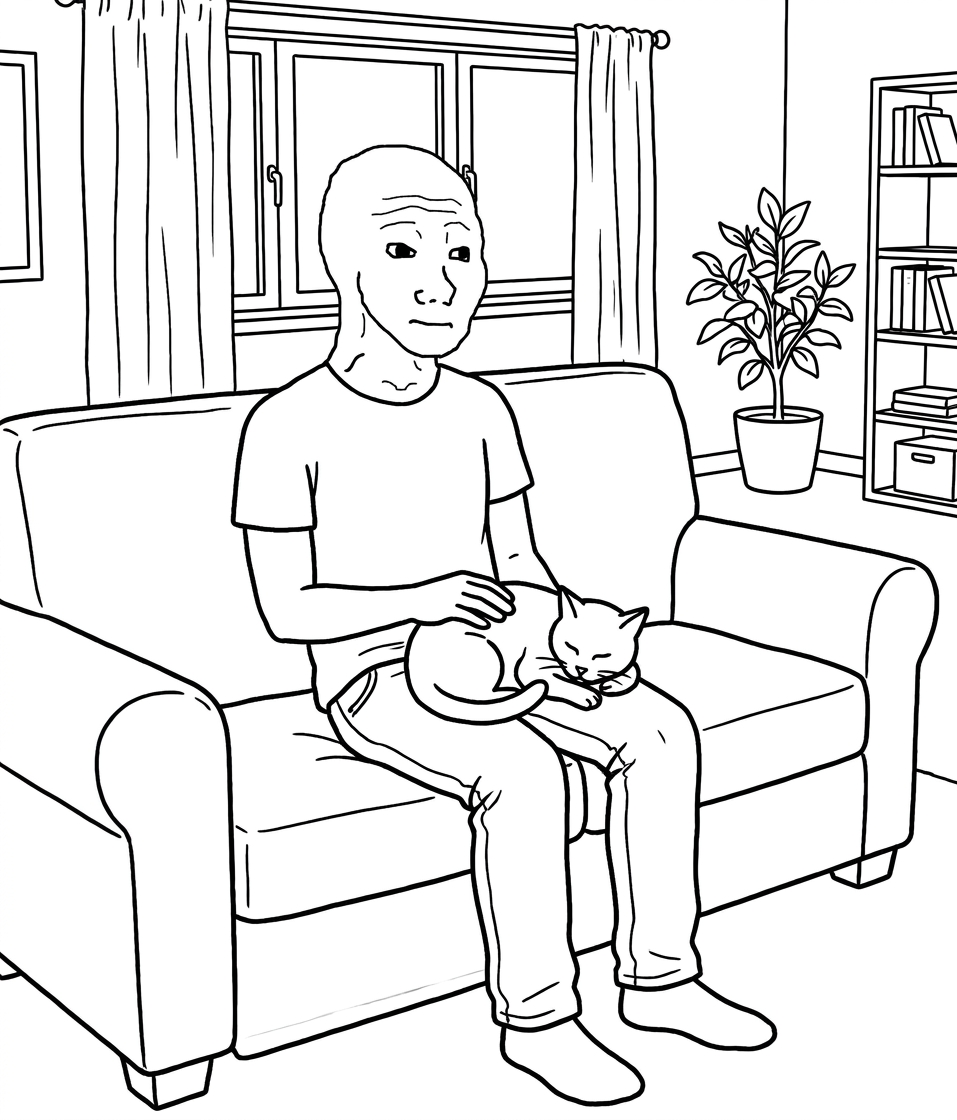
One reference picture of a character and one fixed scene: that same character, in that same style, sitting on their living room sofa stroking their cat, seen head to feet. The prompt never says what the reference is, so the model has to read the style itself — and then invent an entire body, outfit and room that the reference never showed. The failure that makes it worth recording is the model that draws it beautifully instead of faithfully.
2 videos featuring this round
Rounds stay open: later videos added their new models to this one.


The prompt every model got
The attached image shows a character.
Draw that same character sitting on the sofa in their own living room, stroking their cat. Front view: they face the viewer, and all of them is in frame, head to feet.
Match the attached image exactly in style. Whatever it is made of — the medium, the line quality, the amount of detail, the color palette, the way shading is or is not done — your image is made of the same thing. If the attachment is flat black linework on white, so is yours. If it is painted, or shaded, or photographic, so is yours.
The character keeps their face and stays recognizably the same person. Everything the attachment does not show, you invent: the rest of their body if only part of it is visible, what they are wearing, the sofa, the room around them, and the cat.
No text, captions, signatures, watermarks, borders or panel frames anywhere in the image.
Answers
Sorted by cost. Open a row to load its answer.